Pro Model Self-Host
- Same model as the API: same weights, same results (MAE 0.0574 on our 37-image benchmark)
- You own the deployment: on-premise or in your own cloud account
- Images stay with you: nothing is sent to withoutBG
- Requires an NVIDIA GPU with CUDA support
- €3,600 + VAT, one-off flat fee: perpetual license with 12 months of updates (license terms)
Self-hosted · Commercial license
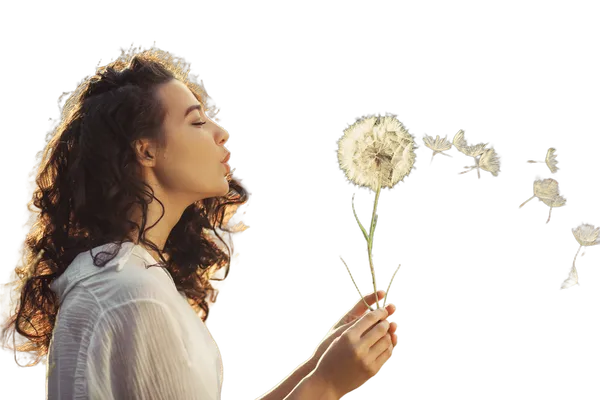
Licensed from Adobe Stock. Asset ID: 225907703
How it compares#
Both withoutBG models scored on the same 37 photos with ground-truth alpha mattes. Lower is better on every metric. Pro Model Self-Host is the same model as Pro Model API, so the numbers are the same whether you run it yourself or call the API. Its MAE is 4.6% higher than the free open-weights model.
| Model | MAE | Edge (MGE) | Connectivity | Runs on | License |
|---|---|---|---|---|---|
| Pro Model (Self-Host or API) | 0.0574 | 0.0615 | 0.0572 | Your infrastructure, or withoutBG cloud (Frankfurt) | Commercial license, or pay per image |
| Open weights | 0.0549 | 0.0621 | 0.0545 | Your infrastructure | Free, open model license |
Examples#
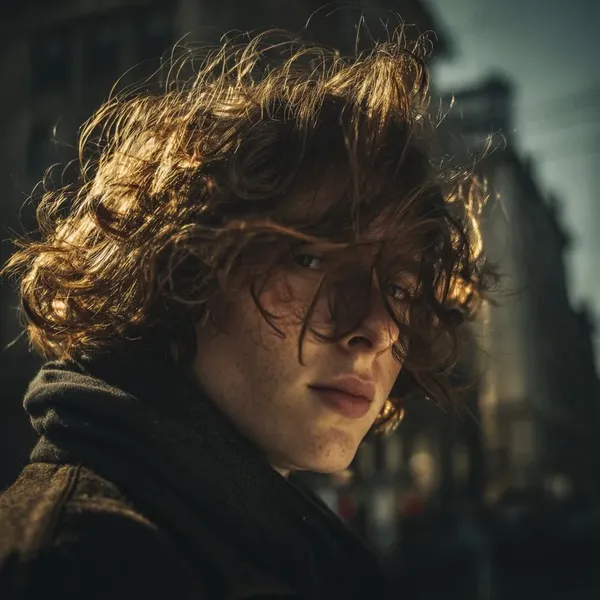
Sample outputs from the Pro Model, identical on the API and Self-Host. Switch between transparency, chroma key, and alpha matte on each result.
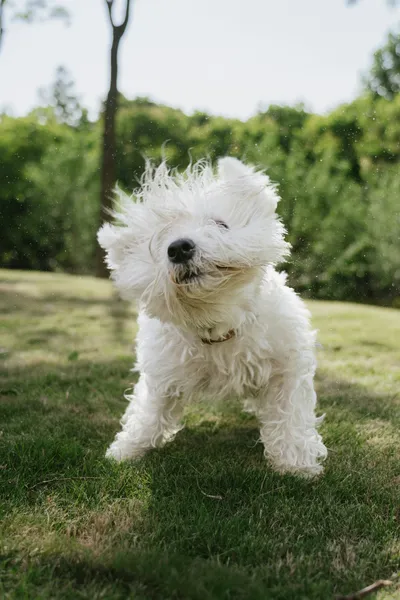
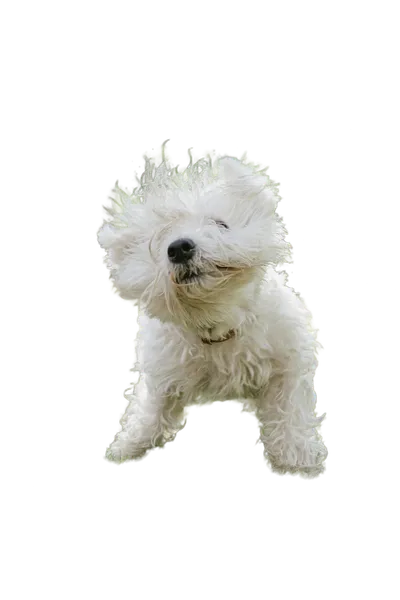
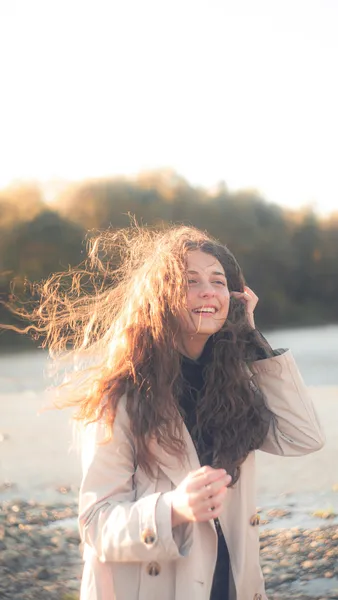
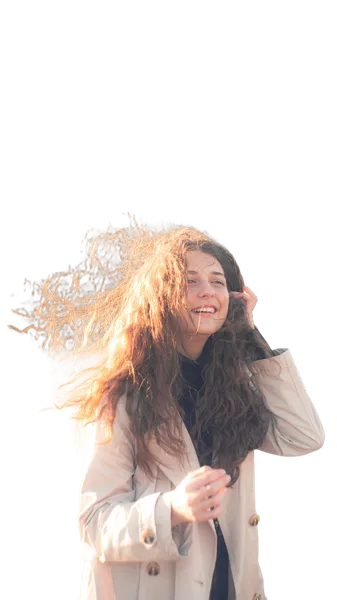
Photo by Niko Tsviliov on Unsplash
API or Self-Host?#
Same model, same outputs. The only difference is who runs the infrastructure.
- Pro Model API: nothing to run. We host, scale, update and monitor the model; you pay per image.
- Pro Model Self-Host: you run it. You provide the hardware (an NVIDIA GPU with CUDA support), deploy, scale and keep the model running; you pay €3,600 + VAT once, and images never leave your network.
When to choose Pro Model Self-Host#
- Images can't leave your network. Contracts, regulation or internal policy rule out a third-party API. Pro Model Self-Host runs inside your own infrastructure.
- You want Pro Model quality without sending images out. The open-weights model is free to self-host; Pro Model Self-Host gives you the API's model in the same setup.
- You want to own it. The model runs on your servers, next to your storage and pipelines, with no dependency on a third-party service.
If you'd rather not run infrastructure, Pro Model API is the same model, fully managed.
Requirements#
What a server needs to run Pro Model Self-Host. The model runs on TensorRT, so it needs an NVIDIA GPU; there is no CPU-only mode.
| Delivery | A Docker image (9.95 GB). On first start it builds a TensorRT engine for the GPU it runs on. |
|---|---|
| GPU | One NVIDIA GPU, Turing generation or newer (for example T4, RTX 20/30/40 series, A10G, L4, A100, H100). Tested on the NVIDIA T4, the GPU we run in production. 8 GB of GPU memory minimum, 16 GB recommended. |
| CPU and RAM | 4 CPU cores and 16 GB of RAM. |
| Disk | 30 GB free for the Docker image (9.95 GB) and the runtime. |
| Software | Linux (x86_64), NVIDIA driver 525 or newer, Docker with the NVIDIA Container Toolkit. |
| Network | None to withoutBG. It runs offline and sends no telemetry. |
| Images | Up to 25 megapixels and 5000 px on the long side. Larger images are scaled down first. |
| Scaling | Each GPU processes one image at a time and queues the rest. Add GPUs or servers for more throughput. |
Get a license#
The license is €3,600 + VAT, one-off. Tell us about your deployment target and your timeline, and we'll reply with the Order Form. The license terms page sums up what the license allows.